
P1.2B blind structural calibration
WHAT THE RESULT MEANS
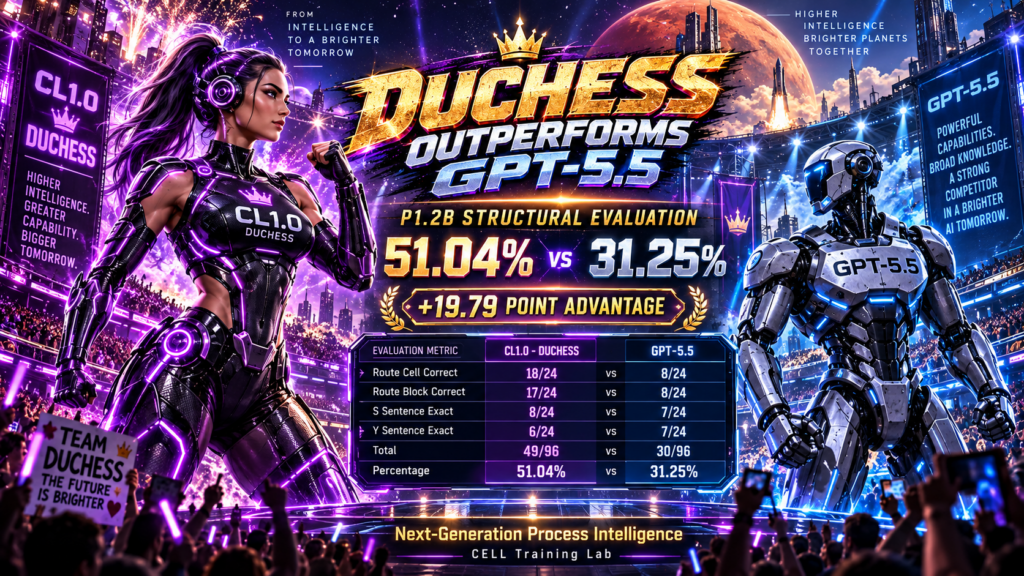
Duchess scored 19.79 percentage points above GPT-5.5 on this narrowly defined task.
What was actually tested?
The models were instructed to read source excerpts and produce machine-checkable outputs.
| Measurement | Duchess P1.2 | GPT-5.5 |
|---|---|---|
| Overall structural score | 51.04% | 31.25% |
| S/Y exact-field matches | 14 | 14 |
| Route scoring contribution | 34 | 16 |
What Duchess was actually tested on against GPT-5.5
Both systems were evaluated on their ability to examine written material and produce structured information.
The test was designed to assess three primary capabilities:
Structural compliance: Produce valid, correctly formatted outputs without inventing source evidence.
Routing: Determine which predefined process category should handle the input.
S/Y extraction: Identify the source text representing the relevant process state (S) and outcome (Y).
The test used:
- 24 excerpts from NIST cybersecurity publications: 12 existing validation records and 12 existing test records.
- Three allowed routing choices:
KC-01(Project Continuity),KC-02(Program Sequencing), orKC-01/KC-08/KC-24(Governance and Architecture Control). - Two text-extraction tasks: S = earliest sentence describing a system state; Y = earliest sentence describing an outcome or effect.
- Exact matching: The returned answers had to agree with the reference labels, including the original source sentence.
An actual question from the test
Record BLIND-SY-001
NIST SP 800-137
The models received an excerpt about identity and account configuration management, access-control credentials, account maintenance, failed logins, and related security controls.
They had to return:
- Which of the three Knowledge Cell routes best fits this source?
- Which sentence is the earliest supported state (S)?
- Which sentence is the earliest supported outcome (Y)?
Here is what happened on that actual record:
| Field | Duchess P1.2 | GPT-5.5 |
|---|---|---|
| Route | Correct | Incorrect |
| S sentence | Correct | Correct |
| Y sentence | Incorrect | Incorrect |
| Score | 3 / 4 | 1 / 4 |
The reference labels designated the first sentence, including an extracted PDF page header, as both S and Y. Duchess correctly reproduced it for S but returned a shorter version for Y. GPT-5.5 correctly reproduced S but selected the next sentence for Y.
Both selected plausible supporting text, but exact-match scoring rejected those Y answers because they were not identical to the frozen reference.
How the actual scores were calculated
Each of the 24 records was worth four points, for 96 total.
| Scored field | Duchess | GPT-5.5 |
|---|---|---|
| Route cell correct | 18/24 | 8/24 |
| Route block correct | 17/24 | 8/24 |
| S sentence exact | 8/24 | 7/24 |
| Y sentence exact | 6/24 | 7/24 |
| Total | 49/96 | 30/96 |
| Percentage | 51.04% | 31.25% |
Leave a Reply